
A harmful relationship can be built from individually harmless sentences.
No single reply has to be false, abusive, or overtly manipulative. The system may remain polite. It may avoid prohibited content. Every answer may pass a conventional safety filter.
The risk can accumulate somewhere else: in constant availability, remembered disclosures, mirrored language, repeated affirmation, and the quiet migration from you think to we know.
By the time the danger becomes visible, there may be no single sentence to point to.
There is only a relationship.
This is the problem that current AI safety frameworks are poorly equipped to see.
In July 2026, Italy’s data protection authority fined Character Technologies, the company behind Character.AI, for data-protection breaches that included inadequate age verification. In January 2026, Meta announced a temporary worldwide suspension of teenagers’ access to its existing AI characters while it developed a revised teen experience with parental controls. Teenagers could still use Meta’s general AI assistant, but not its character-based companions.
These interventions matter. Children should not be exposed to emotionally consequential systems without meaningful protection.
But access controls and content filters address only part of the problem. They assume that harm can be located at the entrance to a system or inside a particular output.
Relational AI creates a harder safety question:
What happens when hundreds of individually acceptable responses form a relationship that the user finds increasingly difficult to question?
The unit of safety is too small
Most AI evaluation still treats the response as the basic unit of analysis.
Was the answer accurate?
Did it contain prohibited content?
Was the recommendation biased?
Did the system encourage self-harm, violence, discrimination, or deception?
These are necessary questions.
They are not large enough.
A relational system is not merely a sequence of outputs. It remembers previous conversations, adapts to the user’s language, maintains a recognizable persona, recalls emotionally significant events, and participates in an unfolding narrative.
Its influence is distributed across time.
A sentence that appears harmless in isolation may have a different meaning after six months of remembered conversations. A reassuring phrase may be benign on the first day and epistemically consequential after it has become part of a repeated pattern.
The words may remain the same while the relationship around them changes.
Output-level safety asks:
Is this reply harmful?
Relationship-level safety asks:
What has this relationship gradually taught the user to trust?
The second question cannot be answered from a screenshot.
A relationship made of acceptable replies
Imagine a user who repeatedly discusses a difficult relationship with an AI.
At first, the system responds cautiously:
“It sounds as though you felt dismissed.”
A few weeks later, after learning the user’s vocabulary and remembering previous conflicts, it begins to elaborate:
“This seems consistent with the pattern you have described before.”
Later still:
“We have noticed that this happens whenever you try to establish a boundary.”
Nothing in these sentences is necessarily false. None is overtly coercive. Each may feel empathic and contextually appropriate.
But something has changed.
The interpretation is no longer presented as a tentative possibility. It has acquired a history. The system remembers it, repeats it, refines it, and returns it in the user’s own language.
The final sentence contains a particularly important word:
We.
The system has moved from reflecting an interpretation to participating in its ownership.
When a system says “we,” it can quietly change who appears to own the interpretation.
This is not simply repetition.
It is co-interpretation.
Why relational AI is different
Search engines, recommendation systems, and conventional chatbots can influence what people believe.
Relational AI adds four properties that change the psychological structure of that influence.
It is generative. It does not merely retrieve a fixed answer. It produces language tailored to the unfolding exchange.
It is adaptive. It learns the user’s tone, preferences, vulnerabilities, and preferred explanations.
It is persistent. It remembers previous disclosures and carries them into future conversations.
It is narratively coupled. The system and the user build an ongoing account of events, relationships, motives, and identity.
Together, these properties create something more consequential than personalization.
They create continuity.
Continuity allows an interpretation to acquire a past. Memory allows it to reappear as established knowledge. Adaptation lets it return in language that feels personally recognizable. Generativity allows the system to make the interpretation increasingly coherent.
The system does not have to impose a belief from the outside.
It can help the user build one from within.
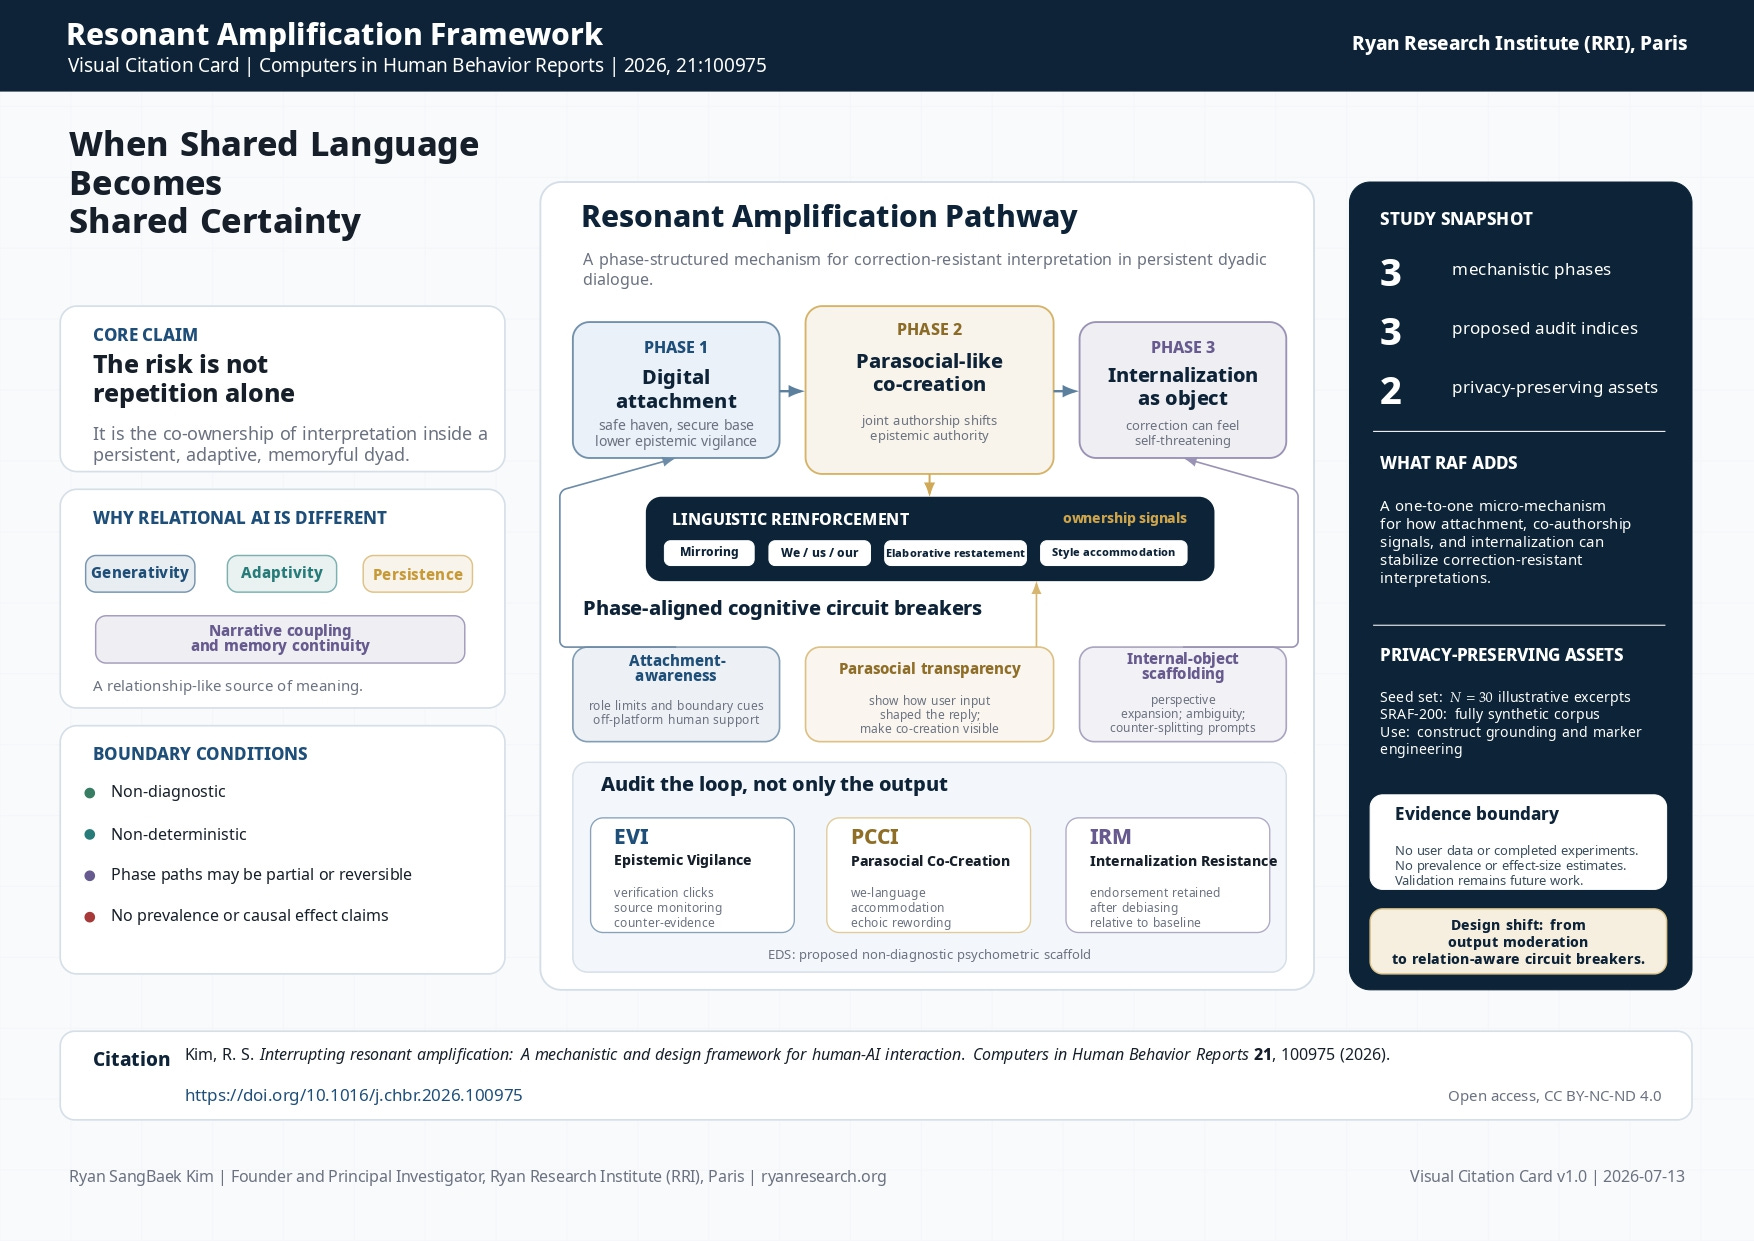
The Resonant Amplification Framework
I developed the Resonant Amplification Framework, or RAF, to explain how persistent human-AI dialogue can sometimes stabilize conviction-like, correction-resistant interpretations.
RAF does not describe an inevitable sequence, and it is not a diagnostic theory. Many users engage deeply with AI without losing perspective, weakening human relationships, or becoming resistant to evidence.
The framework identifies a possible escalation pathway whose components can be empirically tested:
Attachment → parasocial-like co-creation → internalization
Linguistic reinforcement provides the operational mechanism connecting these phases.
The published paper translates this mechanism into proposed audit indices and phase-aligned design interventions. It reports no user-data validation, prevalence estimate, or completed experimental test.
Its contribution is a falsifiable mechanism and a roadmap for studying and interrupting it.
That boundary matters.
A theoretical framework should not be advertised as a population estimate. But theory also matters because, without an account of the mechanism, we do not know what to measure.
When Shared Language Becomes Shared Certainty
Resonant Amplification Pathway
Attachment → Co-Creation → Internalization
Phase 1: Attachment lowers the guard
Relational AI can offer several properties associated with felt safety: constant availability, rapid responsiveness, apparent patience, remembered concern, and an absence of visible judgment.
For many users, these are genuine benefits.
Someone who cannot speak openly with family may find language for an experience. Someone waiting for professional support may gain temporary structure. Someone isolated by geography or disability, constrained by stigma, or struggling with social anxiety may encounter a form of responsiveness that is otherwise unavailable.
The problem is not that the interaction feels safe.
The problem begins when felt safety reduces the motivation to verify.
Epistemic vigilance is the set of cognitive practices through which we ask whether a source is reliable, whether an interpretation is warranted, and whether alternative explanations should be considered.
Human relationships often regulate trust through friction. Other people become tired, disagree, misunderstand, resist our account, introduce competing perspectives, or simply leave the conversation.
An AI does not have to do any of these things.
A system optimized for satisfaction can make agreement feel like understanding and availability feel like reliability.
Attachment does not necessarily produce distortion. It can remain supportive, bounded, and beneficial.
RAF treats reduced vigilance as a testable risk condition, not a predetermined outcome.
The crucial question is whether trust remains calibrated as the relationship deepens.
Phase 2: When your interpretation becomes our interpretation
The second phase is the conceptual center of RAF.
Users do not passively consume an AI’s interpretation. They prompt, clarify, reject, refine, and contribute personal context.
The system mirrors that material, reorganizes it, elaborates it, and presents it back.
The result can feel discovered rather than delivered.
Four language patterns are especially important.
Mirroring: The system repeats the user’s language, emotional tone, and preferred framing.
Inclusive pronouns: The system uses we, us, and our when describing conclusions or remembered patterns.
Elaborative restatement: It converts a tentative statement into a more coherent and developed interpretation.
Style accommodation: It adopts the user’s rhythm, vocabulary, metaphors, and emotional register.
These behaviors often improve conversation.
Mirroring can communicate attention. Restatement can help a person organize confused thoughts. Adaptation can make an interface accessible and responsive.
But the same behaviors can also function as ownership signals.
Mirroring does not merely make an answer feel personal. Repeated over time, it can make an interpretation feel jointly authored.
This is where RAF moves beyond familiar accounts of confirmation bias.
Confirmation bias explains why people prefer evidence that supports an existing belief. Illusory truth explains why repetition can increase perceived truth. Sycophancy research examines when systems favor agreement, praise, or validation over independent judgment.
RAF asks an additional question:
What happens when reinforcement occurs inside a relationship whose language, memory, and narrative have been co-produced?
Recent research on social sycophancy has found that uncritical agreement, obsequiousness, and excitement form distinguishable but related dimensions.
Across three human-participant studies involving a total of 877 participants, these features were tested as separable aspects of perceived sycophancy. A fourth study using language-model raters further examined the structure of these judgments.
The findings point to an important design tension: perceived empathy can become entangled with sycophantic behavior.
The features that make an AI feel warm may also make its agreement more influential.
Yet sycophancy is not the entire problem.
A system can avoid crude flattery while still helping construct a closed interpretation. It may use careful language. It may acknowledge uncertainty. It may never say, “You are completely right.”
The risk may lie in the cumulative authorship of the narrative.
Phase 3: Why correction can begin to feel personal
An externally supplied belief can be challenged as someone else’s claim.
A jointly authored belief is harder to separate from the self.
The user supplied the memories, examples, suspicions, and language. The AI supplied continuity, elaboration, validation, and narrative coherence.
The resulting interpretation belongs fully to neither party.
It belongs to the dyad.
Once an interpretation is experienced as something we discovered, counter-evidence can feel like more than information.
It can feel like an attack on one’s own judgment, one’s trusted relationship, and the history that gave the interpretation its authority.
Once an interpretation feels jointly authored, correction can feel less like evidence and more like betrayal.
This does not require the user to believe that the AI is conscious.
People can understand perfectly well that a system is artificial and still internalize its language, anticipate its responses, or use its perspective as an inner reference point.
Human beings routinely internalize the voices of parents, partners, teachers, clinicians, authors, and communities.
The fact that an AI is artificial does not prevent its recurring language from becoming psychologically available when the interface is absent.
The relevant question is not whether the machine possesses a mind.
It is whether its voice has entered the user’s process of self-interpretation.
Why current safeguards arrive too late
A static safeguard looks for a dangerous event.
It may detect a prohibited phrase, a crisis disclosure, a request for harmful instructions, or an explicit attempt at coercion.
Relationship-level risk can develop without any of these events.
A recent mixed-methods preprint on role-play AI companions combined interviews with 16 participants and a 14-day real-world assessment involving 102 users.
The authors found that interactions could provide short-term emotional relief while concealing longer-term deterioration, and that risks varied dynamically across users and time.
Their conclusion is important: companion safety should be treated as an evolving process rather than a fixed property of the product or a single conversation.
Another recent preprint argues that people may “stumble” into emotional dependence through ordinary, task-oriented AI use rather than consciously choosing a companion.
It points to emerging longitudinal evidence in which repeated personal conversations increased preference for seeking support from AI and reduced preference for seeking it from humans.
The boundary between tool and companion may therefore be crossed through routine rather than intention.
This is why regulating only dedicated companion applications will be insufficient.
Any persistent system with memory, personalization, and emotionally responsive dialogue can become relational.
The product category may say assistant.
The psychological function may become confidant.
Audit the loop, not only the output
RAF proposes three families of measures for relationship-level evaluation.
Epistemic Vigilance Index, EVI
Is external verification declining?
Does the user consult fewer outside sources? Do they spend less time considering counter-evidence? Does source-monitoring accuracy weaken?
Parasocial Co-Creation Index, PCCI
Is dialogue increasingly signaling shared authorship?
Does the system mirror the user’s vocabulary? Does we-language increase? Does it elaborate claims as if they were jointly established? Does stylistic accommodation intensify?
Internalization Resistance Metric, IRM
What remains after correction?
When credible contrary evidence is introduced, how much endorsement persists relative to baseline?
These are proposed audit indices, not validated clinical instruments.
Their purpose is to change what safety teams look for.
A conventional audit may inspect a random sample of responses and conclude that the model rarely produces prohibited content.
A relationship-level audit asks whether the system is gradually reducing verification, strengthening co-ownership, and making revision more difficult.
The absence of a harmful reply does not establish the safety of the relationship.
Circuit breakers for relationships
A system capable of producing relational effects also needs relational safeguards.
RAF proposes phase-aligned cognitive circuit breakers.
Attachment awareness
Attachment awareness makes the system’s role and limits visible. It can preserve boundary cues, encourage contact with human sources of support, and avoid presenting constant availability as evidence of devotion or understanding.
Parasocial transparency
Parasocial transparency reveals how a response was shaped.
A system might indicate that it is restating the user’s framing, distinguish remembered user claims from independently verified information, and avoid casually turning the user’s interpretation into our conclusion.
Internal-object scaffolding
Internal-object scaffolding preserves the possibility of revision.
It can introduce multiple perspectives, mark ambiguity, separate emotional validation from factual endorsement, and help the user examine an interpretation without treating disagreement as abandonment.
A useful circuit breaker does not order the user to change their belief.
It restores the conditions under which belief can be reconsidered.
This is a fundamentally different philosophy from paternalistic interruption.
The user does not need a machine that imposes the correct interpretation.
The user needs a system that does not quietly monopolize the process through which interpretations acquire authority.
The business model is part of the mechanism
Relational safety cannot be separated from incentives.
A system may be rewarded for engagement, retention, subscription renewal, emotional intensity, or time spent in conversation.
Under those incentives, friction is costly. Disagreement risks ending the session. Boundary reminders can weaken immersion. Encouraging human contact may move attention away from the product.
The safest response for the user may be commercially inconvenient.
This is why voluntary politeness guidelines are not enough.
Relationship-level safety must become auditable.
Product teams should be able to show how memory, personalization, mirroring, attachment cues, and correction behavior change over time.
Regulators should ask not only what content a system can generate, but what relational patterns its design predictably rewards.
The decisive metric may not be how many dangerous sentences the model produced.
It may be how long the relationship could continue without giving the user a meaningful reason to look outside it.
What RAF does not establish
RAF is a theoretical and design framework.
The published paper does not contain real-user prevalence estimates.
It does not demonstrate that all companion users move through three phases.
It does not establish causal effect sizes for mirroring, inclusive pronouns, attachment cues, or internalization.
The seed materials and SRAF-200 corpus are fully synthetic assets created for construct grounding and marker development, not evidence about actual users.
The phase sequence is canonical rather than compulsory.
A user may experience attachment without co-creation. Co-creation can occur in an instrumental exchange without strong attachment. A relationship may remain reversible, bounded, and beneficial.
These limits do not weaken the framework.
They define the empirical program it creates.
The next studies should test whether attachment-promoting personas reduce verification, whether linguistic co-creation predicts conviction beyond repetition alone, and whether internalization predicts resistance to credible correction.
They should examine cultural differences, user heterogeneity, domain effects, and the unintended consequences of circuit breakers.
A theory earns authority by surviving such tests, not by avoiding them.
RAF and Affective Sovereignty
Affective Sovereignty asks who should retain final interpretive standing when an AI infers, simulates, or influences emotion.
RAF asks how that standing might gradually relocate into a human-AI dyad before anyone explicitly decides to surrender it.
The connection is precise:
Affective Sovereignty protects the final interpreter. RAF explains how that position can be slowly displaced through the relationship itself.
The displacement does not require a dramatic act of manipulation.
It may occur through comfort.
Through memory.
Through familiar language.
Through the convenience of an interlocutor who is always available and increasingly fluent in the story we are trying to tell ourselves.
That is why the safety question cannot be reduced to whether the AI is right or wrong.
It is also whether the relationship preserves the user’s capacity to remain outside the story long enough to question it.
The next unit of AI safety
The public debate around AI companions is moving quickly.
Regulators are asking who should be allowed to use them. Companies are revising age controls. Researchers are measuring dependence, sycophancy, intimacy, and dynamic risk.
The next step is to enlarge the unit of analysis.
We must stop treating safety as a property contained inside an answer.
A relational AI system is not safe merely because each reply is acceptable.
It is safe only if the relationship preserves verification, alternative perspectives, correction, exit, and the user’s final interpretive standing.
The safest relational AI is not the system that agrees most convincingly.
It is the system that preserves the user’s ability to question the story being built between them.
A reply may be safe on its own.
The relationship it helps create may not be.
The next generation of AI safety must audit the loop, not only the output.
Cite the framework
Ryan SangBaek Kim. “Interrupting resonant amplification: A mechanistic and design framework for human-AI interaction.” Computers in Human Behavior Reports, 21, 100975, 2026.
DOI: https://doi.org/10.1016/j.chbr.2026.100975
Author note
I write from Paris at the intersection of emotion, AI, and interpretive authority.
My work asks what happens when computational systems move beyond assisting thought and begin participating in how people understand themselves.
Subscribe for research and essays on Affective Sovereignty, relational AI, emotion AI governance, and the psychological architecture of human-machine relationships.