
A paper has been published.
It carries a dry title — “Formal and Computational Foundations for Implementing Affective Sovereignty in Emotion AI Systems” — and it sits in a Springer Nature journal called Discover Artificial Intelligence, open access, available to anyone with an internet connection. But the question it asks is not dry at all. It is, in fact, one of the oldest questions humans have ever faced, dressed now in the language of cost functions and runtime protocols:
When a machine tells you what you feel, and you disagree — who wins?
To understand why this question matters, you have to understand something that psychology, psychiatry, and psychoanalysis have each treated as obvious — so obvious that no one thought to protect it.
In psychology, the self-report is the starting point. When a researcher measures emotion, the first instrument is the subject’s own account. Not because self-reports are infallible — they are shaped by language, culture, fatigue, social desirability — but because no external measurement carries authority without first passing through the subject’s testimony. A facial electromyogram can register muscle activation. It cannot tell you what that activation means to the person whose face it is. The field treats self-report as the gold standard for validating every other measure of subjective experience (Frontiers in Psychology, 2024; PMC, 2023).
In psychiatry, the patient’s subjective complaint opens the clinical encounter. The “S” in the SOAP note — Subjective — comes first for a reason. A psychiatrist may observe flat affect, psychomotor retardation, pressured speech. But diagnosis begins with the patient’s own account: what hurts, what frightens, what keeps them awake. The clinician holds diagnostic authority, yes. But even that authority is constrained by a training that teaches, over years, to listen before naming.
In psychoanalysis, the principle is older and more radical. The analyst offers interpretation; the analyst does not impose it. Analytic neutrality — the posture Freud described and generations of clinicians refined — means that the meaning of a feeling is constructed between two people, not delivered from one to the other. When interpretation is forced, the analytic process does not merely fail. It ceases to be analysis. It becomes something else: suggestion, coercion, power dressed as care.
Three disciplines. Three traditions. One shared architecture: the person experiencing the emotion holds a privileged, if not absolute, position in the construction of its meaning.
But here is what none of them noticed, because it seemed too self-evident to notice: that privilege was never formally secured. It was a clinical habit, a methodological convention, a therapeutic ethic. It was never a design principle. It was never encoded. It was never given teeth.
And there is a deeper truth that complicates even this picture.
The authority to interpret emotion has never, in the full sweep of human history, actually belonged to the person who feels it. In ancient Mesopotamia, priests read the entrails of animals and the movements of stars to determine whether a king’s grief was divine punishment or a sign of favor. In medieval Europe, confessors decided whether a penitent’s sorrow was genuine contrition or mere attrition — and the distinction determined whether you were absolved or damned. In the nineteenth century, the asylum physician classified your distress into categories you had no voice in constructing. Hysteria was not what you felt; it was what the doctor saw.
The twentieth century changed this — partially, unevenly, incompletely. Humanistic psychology, the deinstitutionalization movement, the ethics of informed consent, the slow professionalization of psychotherapy — these shifts did not hand interpretive authority to the individual. They created a negotiated space, a clinical encounter in which the subject’s experience was taken seriously, even if the final word still belonged to the professional.
That negotiated space is what we call respect. It is not sovereignty. It is the best approximation we had.
And now that approximation is eroding.
Emotion AI — systems that infer human feelings from facial expressions, vocal prosody, physiological signals, text patterns, and behavioral traces — has entered domains that were never designed with clinical ethics in mind.
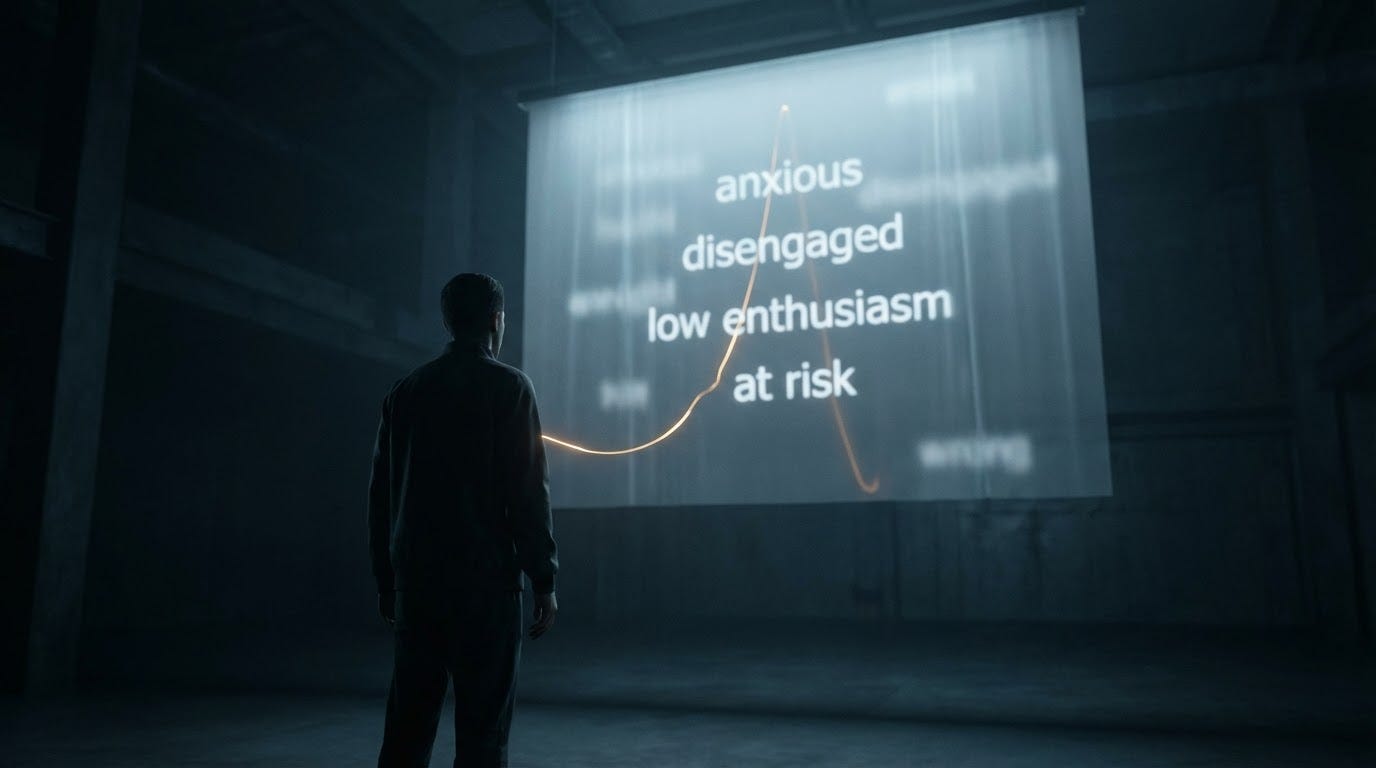
A hiring platform reads a candidate’s face during a video interview and scores her enthusiasm as low. She was nervous, not disengaged. In her cultural context, restraint signals respect. There is no appeals process. The label is in the file, and it outranks her (Kahn, Fortune, 2021 — HireVue dropped facial monitoring only after public audit pressure).
An insurance algorithm flags elevated stress markers in a policyholder’s voice during a claims call. The flag raises the probability of fraud. The policyholder was grieving.
A therapy chatbot interprets a teenager’s messages as indicating low distress and reduces check-in frequency. The teenager was masking — a pattern any trained clinician would recognize, but one that requires relational context the system does not possess.
A social media feed detects sadness in a user’s engagement patterns and serves emotionally activating content to increase time-on-platform. The user does not know this is happening. The system does not pause to ask.
What these examples share is not inaccuracy, though inaccuracy is common. What they share is the structural absence of the subject’s voice at the moment of interpretation. The system infers, labels, and acts — and the person whose inner life is being described has no seat at the table.
Barrett and colleagues (2019, Psychological Science in the Public Interest) demonstrated that inferring emotion from facial movement alone lacks reliable scientific foundation. Stark and Hutson (2021) called such systems “physiognomic AI,” invoking the discredited pseudoscience of reading character from faces. Crawford (2021, Atlas of AI) showed how emotion recognition reproduces power asymmetries at scale.
These are important critiques. But they converge on a single axis: accuracy. They ask whether emotion AI gets it right. The deeper question is what happens when it gets it wrong — or even when it gets it right — and the person disagrees.
That question had no engineering answer.
The academic debate, for nearly three decades, followed a circular pattern.
One camp — beginning with Picard’s foundational Affective Computing (1997) — argued that machines could and should recognize emotions, and that improved algorithms would resolve accuracy concerns. Another camp countered that emotions are constructed, not displayed; that expression is culturally mediated, individually idiosyncratic, and contextually shaped; that no model trained on categorical labels could capture the granularity of lived feeling.
A third current, running alongside both, developed ethical frameworks centered on privacy, transparency, and fairness — principles enshrined in guidelines from the OECD (2019), UNESCO (2021), and now the EU AI Act (Regulation 2024/1689). These frameworks addressed surveillance, bias, and opacity. They did not address the transfer of interpretive authority itself.
The rotation was stable. Improve accuracy. Challenge accuracy. Regulate data handling. Repeat. Hagendorff (2020, Minds and Machines) noted that most AI ethics guidelines converge on the same five principles. Mittelstadt (2019, Nature Machine Intelligence) showed that principles alone cannot guarantee ethical outcomes. But the missing piece was not another principle. It was a mechanism — a design-level answer to the question: where does the right to define emotional meaning reside, and how do you enforce it inside a running system?
That gap is what I tried to fill.
The paper introduces a concept I call Affective Sovereignty: the right of individuals to remain the ultimate interpreters of their own emotions, embedded not as an ethical aspiration but as a structural constraint in the design of emotion AI systems.
This is not a metaphor. The paper decomposes the system’s objective function into three explicit terms. The first is conventional prediction loss — the system’s incentive to be accurate. The second is an interpretive override cost: when the system contradicts the user’s self-report, that contradiction is priced as a loss. The third is a manipulation penalty: when the system’s actions are likely to coerce or shift the user’s emotional state toward a target the user did not choose, the penalty escalates.
The result is a system that pays, mathematically, for ignoring you.
This cost structure is enforced at runtime through a protocol called DRIFT — Dynamic Risk and Interpretability Feedback Throttling. DRIFT is a series of gates. If the system’s confidence is below a threshold, it pauses. If a pending action would violate a policy constraint — say, inferring emotion in a context where it is banned — it halts. If a coercion pattern is detected — a feedback loop in which the system’s outputs are systematically shifting the user’s emotional state — it interrupts. At each gate, the default is not assertion. It is a question: “Is this what you mean?”
In proof-of-mechanism simulations with ten random seeds, enforcing DRIFT reduced the Interpretive Override Score — the rate at which the system contradicts the user — from 32.4% to 14.1%. The repeat-error rate, measuring whether the system makes the same mistake after being corrected, dropped from 36.4% to 13.2%. Roughly 70% of affective decisions were deferred to the user.
That 70% number might look like failure to an engineer optimizing for throughput. I see it as the point. When a system is claiming to know what you feel, deferring to you is not inefficiency. It is structural humility.
These are simulation results. A preregistered human-subject study (n = 48) is planned and has not yet been conducted. The claims are deliberately modest in method. But the framework provides something that did not exist before: a way to measure, in quantified and auditable terms, how much an emotion AI system infringes on its users’ interpretive authority.
Why does measurement matter?
Because today — this very day, February 18, 2026 — Mark Zuckerberg is testifying in a Los Angeles courtroom. The case is a landmark: a woman alleges that Meta’s Instagram and Google’s YouTube, which she used as a child, were intentionally designed to be addictive and harmed her mental health. TikTok and Snap have already settled. Meta and Google are fighting (Reuters, Feb 18, 2026; NPR, Feb 18, 2026; The Guardian, Feb 18, 2026).
The plaintiffs’ lawyers showed jurors internal emails from 2014 and 2015 in which Zuckerberg set goals to increase time spent on the app by double-digit percentage points. The defense argues the woman’s health records point to a troubled childhood. Bereaved parents sit in the gallery. The trial is expected to last six to eight weeks. The verdict could reshape Big Tech’s longstanding legal defense against claims of user harm.
What the plaintiffs lack — and what every similar case has lacked — is a standardized, quantitative measure of how much and how often an algorithmic system overrode, displaced, or manipulated a user’s emotional self-understanding. The evidence is powerful: internal documents, expert testimony, heartbreaking personal accounts. But there is no metric analogous to a blood-alcohol level for emotional infringement. No number a regulator can set as a threshold. No audit trail a compliance officer can check.
The three metrics proposed in this paper — IOS, AMR, and Affective Divergence — are designed to fill that void. They do not solve the legal problem. But they offer a vocabulary: a way to say, with precision, “This system contradicted its user’s self-report 32% of the time, and after correction, repeated the same error 36% of the time.” That is a sentence a court can evaluate. That is a number a regulation can reference. That is an audit a company can be required to perform.
The EU AI Act takes full effect for high-risk AI systems on August 2, 2026. Article 5 already prohibits certain emotion-inference practices in workplaces and educational settings. Article 50(3) imposes transparency obligations on deployers of emotion-recognition systems. But the Act currently lacks runtime enforcement mechanisms — tools that operate inside the system at the moment of inference. DRIFT and the Affective Sovereignty Contract proposed in this paper are designed to operate at precisely that level.
This paper is not the end of the work. It is a single piece in a larger architecture.
A companion study, accepted in Elsevier’s Computers in Human Behavior Reports, examines what happens when AI-offered emotional reassurance does not calm but amplifies: a feedback loop in which the system’s consolation triggers further distress, which triggers further consolation, which accelerates the cycle. The paper proposes cognitive circuit breakers — design mechanisms that detect and interrupt resonant amplification before the loop escapes control.
Four papers currently under review investigate the gap between what people say they feel and what their bodies, narratives, and behaviors reveal — and the conditions under which that gap widens or narrows. These studies, built on a purpose-designed dataset, aim to map the geometry of affective discrepancy: the space between expression and experience that every clinician navigates intuitively but no computational model has yet measured systematically.
Additional work in review addresses the suppression costs of emotional regulation in algorithmic environments, the thermodynamic properties of affective energy and collapse, and the conditions under which defensive language patterns signal not deception but self-protection.
And a book — The Interpreter’s Seat — traces this entire trajectory across 3,700 years: from Babylonian diviners who read emotion in animal livers, through medieval confessors who adjudicated the sincerity of remorse, to diagnostic manuals that classified grief as disorder, to the algorithmic feeds that now infer your mood and adjust your reality accordingly. The manuscript is complete and in publisher review.
The question that runs through all of this work is not whether machines can read emotions. Some can, partially, in constrained contexts. The question is who holds the final authority over what those readings mean — and what happens to human dignity when that authority is transferred, silently, to a system that never learned to listen.
Interpretation is not a technical problem. It is a problem of power.
For most of recorded history, that power belonged to priests, physicians, confessors, and analysts. The twentieth century built a fragile architecture of respect — imperfect, professional, and constrained — that gave the subject a voice, if not the final word. The twenty-first century is watching that architecture dissolve, not through malice but through design choices made without asking who should hold the seat of meaning.
Affective sovereignty is not an abstract right. It is a design constraint, a cost function, a runtime gate, and an auditable metric. It is the engineering expression of a simple conviction: the person living the emotion is the one who gets to say what it means.
The research continues. The questions are not settled. The human-subject data is not yet in. But the formal tools now exist — for the first time — to ask the question precisely, measure the answer, and build systems that defer to the people they serve.
Even the most perceptive machine should remain counsel, never judge.
Paper (Open Access): https://doi.org/10.1007/s44163-026-01000-0
Behind the Paper: https://go.nature.com/4rtVc6K
Simulation Code: https://doi.org/10.5281/zenodo.17987998
한국어
내 감정은 누가 정의하는가
해석, 권위, 그리고 감정 AI의 설계에 관하여
논문 한 편이 공개되었습니다.
제목은 건조합니다 — “Formal and Computational Foundations for Implementing Affective Sovereignty in Emotion AI Systems.” Springer Nature의 Discover Artificial Intelligence 저널에 오픈 액세스로 게재되었고, 인터넷이 되는 곳이라면 누구나 읽을 수 있습니다. 그런데 이 논문이 묻는 질문은 건조하지 않습니다. 사실 인간이 던져온 가장 오래된 질문 중 하나를, 비용 함수와 런타임 프로토콜이라는 언어로 다시 묻고 있을 뿐입니다.
기계가 나의 감정을 말하고, 내가 동의하지 않을 때 — 누구의 말이 이기는가?
이 질문이 왜 중요한지 이해하려면, 심리학과 정신의학, 정신분석이 각각 너무 당연하다고 여겨 보호하지 않았던 것을 먼저 들여다봐야 합니다.
심리학에서 자기 보고는 출발점입니다. 연구자가 감정을 측정할 때 첫 번째 도구는 피험자 자신의 진술입니다. 자기 보고가 완벽해서가 아닙니다. 언어, 문화, 피로, 사회적 바람직성에 의해 왜곡될 수 있다는 사실은 누구나 압니다. 그럼에도 어떤 외부 측정도 주관적 경험을 검증할 때 피험자의 보고를 거치지 않으면 권위를 갖지 못합니다. 근전도가 근육 활성화를 기록할 수 있지만, 그 활성화가 당사자에게 무엇을 의미하는지는 말해주지 못합니다. 학계는 자기 보고를 주관적 경험 측정의 기준점으로 다루어 왔습니다(Frontiers in Psychology, 2024; PMC, 2023).
정신의학에서 환자의 주관적 호소는 임상 만남의 문을 여는 열쇠입니다. SOAP 기록의 첫 글자 S — Subjective — 가 맨 앞에 오는 데는 이유가 있습니다. 정신과 의사는 둔마된 정동, 정신운동 지연, 압박된 언어를 관찰할 수 있습니다. 그러나 진단은 환자 자신의 이야기에서 시작됩니다. 무엇이 아프고, 무엇이 두렵고, 무엇이 잠을 빼앗는지. 진단 권한은 임상의에게 있습니다. 그러나 그 권한조차 수년간의 훈련이 가르치는 하나의 윤리에 의해 제한됩니다 — 이름 붙이기 전에 먼저 들을 것.
정신분석에서 원칙은 더 오래되었고 더 급진적입니다. 분석가는 해석을 제안합니다. 강요하지 않습니다. 프로이트가 기술하고 이후 세대가 다듬은 분석적 중립성이란, 감정의 의미가 두 사람 사이에서 구성되는 것이지 한 사람이 다른 사람에게 전달하는 것이 아니라는 자세입니다. 해석이 강요되면 분석 과정은 단순히 실패하는 것이 아닙니다. 분석이 아닌 다른 것이 됩니다 — 암시, 강압, 돌봄의 외양을 입은 권력.
세 분야. 세 전통. 하나의 공유된 구조: 감정을 경험하는 사람이 그 의미 구성에서 특권적이지는 않더라도 우선적인 위치를 갖는다.
그런데 아무도 알아차리지 못한 것이 있습니다. 너무 자명해서 알아차릴 필요가 없었기 때문입니다. 그 특권은 한 번도 정식으로 보장된 적이 없었습니다. 임상의 관습이었고, 방법론의 관례였고, 치료의 윤리였습니다. 설계 원칙이었던 적은 없었습니다. 코드에 기록된 적도 없었습니다. 이빨이 있었던 적도 없었습니다.
이 그림을 한 겹 더 복잡하게 만드는 진실이 있습니다.
감정을 해석할 권한은, 인류 역사 전체를 통틀어, 단 한 번도 감정을 느끼는 당사자에게 실질적으로 귀속된 적이 없었습니다. 고대 메소포타미아에서 사제들은 동물의 내장과 별의 움직임을 읽어 왕의 슬픔이 신의 벌인지 은총의 징표인지를 판정했습니다. 중세 유럽에서 고해신부는 참회자의 슬픔이 진정한 통회인지 단순한 불완전 통회인지를 결정했고, 그 구분이 사면과 저주를 갈랐습니다. 19세기에 수용시설의 의사는 환자의 고통을 환자가 만들지 않은 범주로 분류했습니다. 히스테리는 환자가 느끼는 것이 아니었습니다. 의사가 보는 것이었습니다.
20세기가 이를 바꾸었습니다 — 부분적으로, 고르지 않게, 불완전하게. 인본주의 심리학, 탈수용화 운동, 사전 동의의 윤리, 심리치료의 전문화 — 이 흐름들이 해석 권한을 개인에게 넘긴 것은 아닙니다. 주체의 경험이 진지하게 다루어지는 협상의 공간, 즉 임상적 만남을 만들어냈을 뿐입니다. 최종 발언권은 여전히 전문가에게 있었습니다.
그 협상의 공간을 우리는 존중이라 부릅니다. 주권이 아닙니다. 우리가 가진 것 중 가장 나은 근사치였습니다.
그리고 지금, 그 근사치가 무너지고 있습니다.
감정 AI — 표정, 음성, 생체 신호, 텍스트 패턴, 행동 흔적에서 인간의 감정을 추론하는 시스템 — 가 임상 윤리를 고려하지 않은 영역에 들어왔습니다.
채용 플랫폼이 화상 면접 중 지원자의 표정을 읽고 ‘열정 낮음’이라 점수를 매깁니다. 그 사람은 긴장한 것이지 무관심한 것이 아니었습니다. 그 문화에서 절제는 존중의 표현입니다. 이의 제기 절차는 없습니다. 라벨은 이미 파일에 있고, 본인의 말보다 상위에 놓입니다.
보험 알고리즘이 보험금 청구 통화 중 가입자 목소리의 스트레스 지표를 감지하고 사기 확률을 올립니다. 가입자는 애도 중이었습니다.
치료 챗봇이 십 대의 메시지를 ‘고통 낮음’으로 해석하고 확인 빈도를 줄입니다. 그 십 대는 감추고 있었습니다 — 훈련받은 임상가라면 알아차릴 패턴이지만, 관계적 맥락이 없는 시스템은 포착하지 못합니다.
소셜 미디어 피드가 사용자의 참여 패턴에서 슬픔을 감지하고, 체류 시간을 늘리기 위해 감정적으로 자극적인 콘텐츠를 제공합니다. 사용자는 이 사실을 모릅니다. 시스템은 물어보지 않습니다.
이 사례들이 공유하는 것은 부정확성이 아닙니다. 부정확성은 흔하지만 핵심이 아닙니다. 공유하는 것은 해석의 순간에 주체의 목소리가 구조적으로 부재하다는 사실입니다. 시스템이 추론하고, 이름 붙이고, 행동합니다 — 내면이 기술되고 있는 당사자는 테이블에 자리가 없습니다.
Barrett 등(2019, Psychological Science in the Public Interest)은 얼굴 움직임만으로 감정을 추론하는 것이 신뢰할 만한 과학적 기반을 갖지 못한다고 증명했습니다. Stark와 Hutson(2021)은 이런 시스템을 “관상학적 AI”라 불렀습니다. Crawford(2021, Atlas of AI)는 감정 인식이 권력의 비대칭을 대규모로 재생산함을 보여주었습니다.
중요한 비판들입니다. 그러나 이 비판들은 하나의 축에 수렴합니다: 정확성. 감정 AI가 맞히는가를 묻습니다. 더 깊은 질문은 — 틀렸을 때, 혹은 맞았을 때조차 — 당사자가 동의하지 않으면 어떤 일이 벌어지는가입니다.
그 질문에 대한 공학적 답은 존재하지 않았습니다.
학계의 논쟁은 거의 30년간 순환 구조를 반복했습니다.
한쪽은 — Picard의 Affective Computing(1997)에서 시작하여 — 기계가 감정을 인식할 수 있고 인식해야 하며, 알고리즘이 개선되면 정확도 문제는 해결될 것이라 주장했습니다. 다른 쪽은 감정이 표시되는 것이 아니라 구성되는 것이며, 표현이 문화적으로 매개되고 개인적으로 고유하며 맥락에 의해 형성된다고 반박했습니다.
세 번째 흐름은 두 진영과 나란히 흐르며, 프라이버시·투명성·공정성을 중심으로 윤리 프레임워크를 발전시켰습니다 — OECD(2019), UNESCO(2021), 그리고 EU AI Act(Regulation 2024/1689)에 명문화된 원칙들입니다. 이 프레임워크들은 감시, 편향, 불투명성을 다루었습니다. 해석 권한의 이전 자체는 다루지 않았습니다.
순환은 안정적이었습니다. 정확도를 높여라. 정확도를 의심하라. 데이터 처리를 규제하라. 반복. Hagendorff(2020)는 대부분의 AI 윤리 가이드라인이 같은 다섯 원칙에 수렴함을 지적했습니다. Mittelstadt(2019)는 원칙만으로는 윤리적 결과를 보장할 수 없음을 보였습니다. 그러나 빠진 것은 또 하나의 원칙이 아니었습니다. 메커니즘이었습니다 — 감정적 의미를 정의할 권리가 어디에 있으며, 작동 중인 시스템 안에서 그것을 어떻게 집행할 것인가에 대한 설계 수준의 답.
그 공백이 제가 메우려 한 것입니다.
이 논문은 ‘감정 주권(Affective Sovereignty)’이라는 개념을 제시합니다. 개인이 자신의 감정에 대한 최종 해석자로 남을 권리를, 윤리적 열망이 아니라 감정 AI 설계의 구조적 제약으로 내장하는 것입니다.
비유가 아닙니다. 논문은 시스템의 목적 함수를 세 개의 명시적 항으로 분해합니다. 첫째는 통상적 예측 손실 — 시스템이 정확해지려는 유인입니다. 둘째는 해석 덮어쓰기 비용 — 시스템이 사용자의 자기 보고를 부정할 때, 그 부정이 손실로 가격이 매겨집니다. 셋째는 조작 페널티 — 시스템의 행동이 사용자가 선택하지 않은 감정 상태로 유도할 가능성이 있을 때 벌칙이 상승합니다.
결과적으로 이 시스템은 사용자를 무시하면 수학적으로 비용을 치릅니다.
이 비용 구조는 DRIFT — Dynamic Risk and Interpretability Feedback Throttling이라는 런타임 프로토콜을 통해 실시간으로 집행됩니다. DRIFT는 일련의 관문입니다. 시스템의 확신이 임계치 아래이면 멈춥니다. 대기 중인 행동이 정책 제약을 위반하면 중단됩니다. 강압 패턴이 감지되면 — 시스템의 출력이 사용자의 감정 상태를 체계적으로 이동시키는 피드백 루프 — 끼어듭니다. 각 관문에서 기본값은 단정이 아닙니다. 질문입니다: “이것이 맞습니까?”
10개 랜덤 시드를 사용한 시뮬레이션에서, DRIFT를 적용하자 시스템이 사용자의 해석을 무시하는 비율이 32.4%에서 14.1%로 감소했습니다. 수정 후 같은 오류를 반복하는 비율은 36.4%에서 13.2%로 줄었습니다. 감정 관련 판단의 약 70%가 사용자에게 돌아갔습니다.
70%라는 수치는 처리량을 최적화하는 엔지니어에게는 실패처럼 보일 수 있습니다. 저는 그것이 핵심이라고 봅니다. 시스템이 사용자의 내면을 주장하는 영역에서, 사용자에게 되묻는 것은 비효율이 아닙니다. 구조적 겸손입니다.
이것은 시뮬레이션 결과입니다. 사전 등록된 인간 대상 연구(n=48)는 계획 중이며 아직 수행되지 않았습니다. 방법론적 주장은 의도적으로 절제되어 있습니다. 그러나 이 프레임워크는 이전에 존재하지 않았던 것을 제공합니다: 감정 AI 시스템이 사용자의 해석 권한을 얼마나 침해하는지를, 정량화하고 감사할 수 있는 방식으로 측정하는 도구.
왜 측정이 중요합니까?
오늘 — 바로 이 글이 쓰인 2026년 2월 18일 — 마크 저커버그가 로스앤젤레스 법정에서 증언하고 있기 때문입니다. 이 재판은 역사적 전환점이 될 수 있습니다. 한 여성이 메타의 인스타그램과 구글의 유튜브를 어린 시절 사용하면서 의도적으로 중독성 있게 설계된 플랫폼으로 인해 정신 건강을 해쳤다고 소송을 제기했습니다. 틱톡과 스냅은 이미 합의했습니다. 메타와 구글은 다투고 있습니다(Reuters, 2026년 2월 18일; The Guardian, 2026년 2월 18일; BBC, 2026년 2월 18일).
원고 측 변호사는 2014년과 2015년에 저커버그가 앱 체류 시간을 두 자릿수 비율로 늘리는 목표를 설정한 내부 이메일을 배심원에게 보여주었습니다. 피고 측은 원고의 건강 기록이 어려운 어린 시절을 가리킨다고 주장합니다. 유가족이 방청석에 앉아 있습니다. 재판은 6~8주가 걸릴 것으로 예상됩니다.
원고 측에 없는 것 — 그리고 유사한 모든 소송에 없었던 것 — 은, 알고리즘 시스템이 사용자의 감정적 자기 이해를 얼마나, 얼마나 자주 덮어쓰거나 조작했는지를 보여주는 표준화된 정량적 측정 도구입니다. 증거는 강력합니다: 내부 문서, 전문가 증언, 가슴 아픈 개인 진술. 그러나 감정 침해에 대한 혈중알코올농도에 해당하는 수치는 없습니다. 규제 기관이 임계치로 설정할 수 있는 숫자도 없습니다. 컴플라이언스 담당자가 점검할 수 있는 감사 기록도 없습니다.
이 논문이 제안하는 세 가지 측정 지표 — IOS(해석 덮어쓰기 점수), AMR(수정 후 반복 오류율), 감정 발산도(AD) — 는 그 빈자리를 채우기 위해 설계되었습니다. 법적 문제를 해결하지는 않습니다. 그러나 어휘를 제공합니다: “이 시스템은 사용자의 자기 보고를 32%의 빈도로 부정했고, 수정 후에도 36%의 비율로 같은 오류를 반복했다”고 정밀하게 말할 수 있는 언어입니다. 법정이 평가할 수 있는 문장입니다. 규제가 참조할 수 있는 숫자입니다. 기업에 요구할 수 있는 감사입니다.
EU AI Act는 2026년 8월 2일 고위험 AI 시스템에 대해 전면 시행됩니다. 제5조는 이미 직장과 교육 현장에서의 특정 감정 추론 행위를 금지하고 있고, 제50조 3항은 감정 인식 시스템 운용자에게 투명성 의무를 부과합니다. 그러나 현행 법은 런타임 집행 메커니즘 — 추론이 일어나는 바로 그 순간에 시스템 내부에서 작동하는 도구 — 이 부재합니다. 이 논문에서 제안하는 DRIFT와 감정 주권 계약(ASC)은 정확히 그 수준에서 작동하도록 설계되었습니다.
이 논문은 작업의 끝이 아닙니다. 더 큰 구조물의 한 조각입니다.
Elsevier의 Computers in Human Behavior Reports에 승인된 후속 연구는, AI가 제공하는 감정적 위로가 진정시키지 않고 오히려 증폭시키는 현상을 다룹니다 — 시스템의 위로가 추가 고통을 유발하고, 추가 고통이 추가 위로를 유발하며, 그 순환이 가속되는 피드백 루프. 이 논문은 공명 증폭이 통제를 벗어나기 전에 감지하고 차단하는 인지적 회로 차단기를 제안합니다.
현재 심사 중인 네 편의 논문은 사람들이 느낀다고 말하는 것과 그들의 몸, 서사, 행동이 드러내는 것 사이의 간극을 조사합니다 — 그리고 그 간극이 넓어지거나 좁아지는 조건을 탐구합니다. 목적 설계된 데이터셋을 기반으로 한 이 연구들은 감정 불일치의 기하학을 그리려 합니다: 표현과 경험 사이의 공간, 모든 임상가가 직관으로 항해하지만 어떤 계산 모델도 아직 체계적으로 측정하지 못한 그 영역.
추가로 심사 중인 연구들은 알고리즘 환경에서 감정 조절의 억제 비용, 감정 에너지와 붕괴의 열역학적 속성, 방어적 언어 패턴이 기만이 아니라 자기 보호를 신호하는 조건을 다룹니다.
그리고 한 권의 책 — 해석자들 — 이 3,700년의 궤적 전체를 추적합니다. 동물의 내장에서 감정을 읽던 바빌로니아 점술사로부터, 뉘우침의 진정성을 재판하던 중세 고해신부를 지나, 슬픔을 장애로 분류한 진단 편람을 거쳐, 이제 기분을 추론하고 현실을 조정하는 알고리즘 피드까지. 원고는 완성되었고, 출판사 검토 중입니다.
이 모든 작업을 관통하는 질문은 기계가 감정을 읽을 수 있는가가 아닙니다. 일부는 할 수 있습니다, 부분적으로, 제한된 맥락 안에서. 질문은 그 읽기가 무엇을 의미하는지에 대한 최종 권한을 누가 갖는가 — 그리고 그 권한이 듣는 법을 배우지 못한 시스템에 조용히 넘어갈 때 인간의 존엄에 무슨 일이 일어나는가입니다.
해석은 기술의 문제가 아닙니다. 권력의 문제입니다.
기록된 역사의 대부분 동안, 그 권력은 사제와 의사와 고해신부와 분석가에게 있었습니다. 20세기는 존중의 취약한 구조를 만들었습니다 — 불완전하고 전문적이며 제약된 — 주체에게 목소리를 주었지만, 최종 발언권은 아닌. 21세기는 그 구조가 녹아내리는 것을 지켜보고 있습니다. 악의에 의해서가 아니라, 의미의 자리를 누가 차지해야 하는지 묻지 않은 채 내려진 설계 결정에 의해서.
감정 주권은 추상적 권리가 아닙니다. 설계 제약이고, 비용 함수이고, 런타임 관문이고, 감사 가능한 측정 지표입니다. 단순한 확신의 공학적 표현입니다: 감정을 살아내는 사람이 그 의미를 말할 권한을 갖는다.
연구는 계속됩니다. 질문은 정리되지 않았습니다. 인간 대상 데이터는 아직 들어오지 않았습니다. 그러나 형식적 도구는 — 처음으로 — 존재합니다. 질문을 정밀하게 던지고, 답을 측정하고, 자신이 봉사하는 사람들에게 되묻는 시스템을 만들 수 있는 도구가.
가장 예리한 기계조차, 조언자여야 합니다. 심판관이 되어서는 안 됩니다.
논문 (오픈 액세스): https://doi.org/10.1007/s44163-026-01000-0
Behind the Paper: https://go.nature.com/4rtVc6K
시뮬레이션 코드: https://doi.org/10.5281/zenodo.17987998