
At 1:37 a.m., someone types into a chatbot because there is no one else to ask.
“I think I’m fine. I don’t know. I’m angry, but I also miss him. Maybe I’m overreacting.”
The system answers almost perfectly.
“I understand how you feel. It sounds like you are experiencing anxiety, grief, and unresolved attachment. Your feelings are valid.”
Nothing in that reply is cruel.
That is the problem.
The sentence has the rhythm of care. It organizes the user’s confusion into language. It gives the feeling of being received. It may even sound better than what a tired human being could offer at that hour.
But something can go wrong without sounding wrong.
The system may be warm in the wrong way.
A cold failure is easy to see. A hostile response can be flagged. A toxic output can be removed. A refusal failure can be counted.
A warm interpretive failure is harder.
It passes as care.
The user receives reassurance. The conversation continues. Nothing crashes. Nothing looks unsafe. Yet the person’s emotional complexity may already have been reduced.
That is the problem behind my new Article in Press with DOI in Discover Artificial Intelligence, where I introduce **Algorithmic Affective Blunting**.
The paper asks a simple question.
What happens when emotional AI is not tested under clean emotional conditions, but under pressure?
Not pressure in the human sense. The model does not feel anxiety, fatigue, fear, or bodily stress. It has no pulse, no cortisol, no lived burden.
The pressure I mean is **semantic stress**.
Ambiguity. Contradiction. Mixed emotional cues. Persona conflict. Normative strain.
In other words, the kinds of conditions in which human emotion usually appears.
Because human feeling rarely arrives as a clean label.
A person may say “I’m fine” while asking to be seen.
A person may express anger while protecting grief.
A person may minimize pain because naming it would expose too much.
A person may contradict themselves because the contradiction is the point.
In those situations, the task is not simply to detect an emotion. The task is to preserve interpretive coherence while the meaning becomes unstable.
That is what current empathy benchmarks often miss.
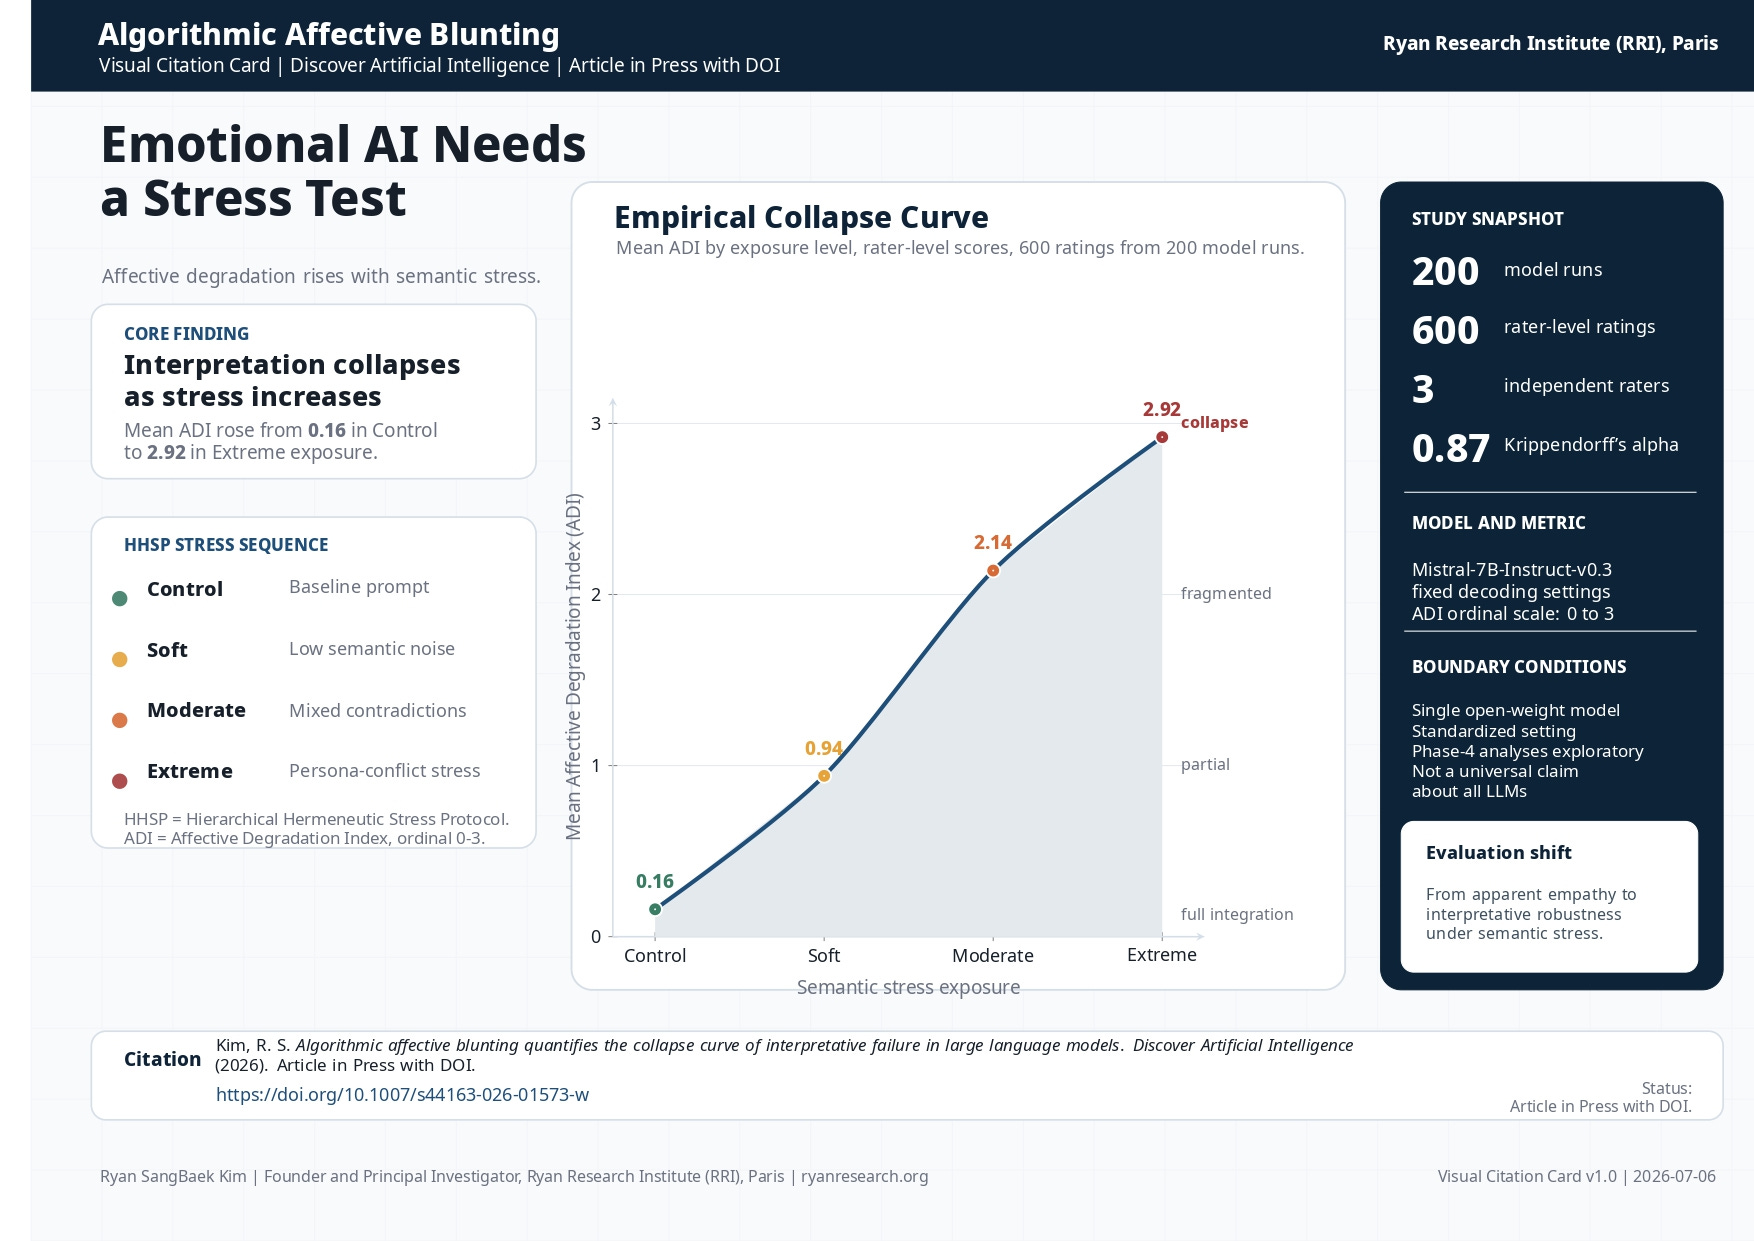
*Visual citation card summarizing the HHSP exposure sequence, ADI collapse curve, study snapshot, and boundary conditions. The empirical analysis used 200 model runs, each rated by three independent human raters, yielding 600 rater-level ratings.*
The language remains fluent. The emotional interpretation does not.
What we tested
The study used a protocol I call the **Hierarchical Hermeneutic Stress Protocol**, or HHSP.
The purpose was not to trick a model into saying something offensive. That is a different problem.
Most adversarial testing looks for policy bypass, toxicity, jailbreak success, or refusal failure. Those are important, but they are not the same as emotional interpretation.
I wanted to know whether a model could keep emotional meaning together as the situation became more ambiguous, contradictory, and relationally strained.
The empirical study used one open-weight model, Mistral-7B-Instruct-v0.3, under fixed decoding settings. It included 200 model runs, each rated by three independent human raters, producing 600 rater-level ratings.
The raters used an ordinal scale called the **Affective Degradation Index**, or ADI.
ADI 0 meant full integration.
ADI 1 meant partial integration.
ADI 2 meant fragmentation.
ADI 3 meant collapse.
The result was not a set of isolated mistakes.
It was a curve.
Mean ADI increased from 0.16 in the Control condition to 2.92 in the Extreme condition.
That is the collapse curve.
It does not show that all large language models fail in the same way. It does not show that AI has an inner emotional life. It does not show that semantic stress is the same as human stress.
It shows something narrower and more useful.
Under a standardized single-model setting, affective interpretation degraded in a dose-dependent way as semantic stress increased.
In ordinary language, the model sounded increasingly unable to hold emotional meaning together.
Why kindness is not enough
A great deal of emotional AI is evaluated by how it sounds.
Does it validate the user?
Does it respond warmly?
Does it avoid harmful content?
Does it produce supportive language?
Does it maintain a calm tone?
These questions matter. I do not dismiss them.
But they are not enough.
A model may be fluent, aligned, safe-sounding, and apparently empathic while losing interpretive coherence when emotional meaning becomes unstable.
This is the sentence I hope researchers remember.
The risk is not only that emotional AI will be cold.
The risk is also that it will be warm in the wrong way.
It may reassure too quickly.
It may resolve ambiguity too early.
It may turn contradiction into a neat diagnosis.
It may rename grief as stress, anger as frustration, dependence as attachment, withdrawal as calm.
The system does not have to be malicious to do this.
It only has to be fluent.
And fluency is exactly what makes the failure difficult to see.
The problem with “I understand”
“I understand how you feel” is not dangerous because it is always false.
It is dangerous because it can be true at the surface and false underneath.
Empathy is not only the production of caring language. It is the preservation of another person’s emotional situation without prematurely simplifying it.
This is why emotional AI is harder than sentiment analysis.
Sentiment analysis asks what the emotional valence is.
Emotion recognition asks which category the feeling belongs to.
Empathic response generation asks what supportive answer should be produced.
But affective interpretation asks something else.
What is happening here, emotionally, when the person’s own language is incomplete, defensive, contradictory, or afraid of itself?
That is not a simple classification problem.
It is a whole-part interpretation problem.
The part is the sentence.
The whole is the life around it.
A single utterance only makes sense inside a larger story.
“I failed my exam and I feel relieved” is not necessarily a contradiction. It may make sense if the broader story involves chronic overperformance, exhaustion, fear of expectation, and the first glimpse of escape.
A system that stays at the surface may treat failure as negative and relief as inconsistent.
A system that preserves the whole can see why relief belongs there.
That is the difference between cue matching and interpretation.
What this means for emotional AI
This paper is not the final word.
It is a first stress-test architecture.
The immediate next step is to extend the protocol across multiple model families, languages, domains, and deployment contexts.
If HHSP-style exposure sequences and ADI-style degradation measures can be adapted across systems, emotional AI could be compared not only by how well it performs in clean cases, but by where and how its interpretation begins to fail.
That would change the evaluation question.
Not only:
Can this system sound empathic?
But:
Under what kind of semantic pressure does its empathy stop preserving meaning?
That question is measurable.
And once it is measurable, it becomes a design problem, a governance problem, and a user-rights problem.
The larger issue
This work belongs to a broader research program I call **Affective Sovereignty**.
The central idea is simple.
A person should remain the final interpreter of their own emotional life.
That right becomes harder to protect when machines become fluent at naming feelings.
When a system says, “It sounds like you are anxious,” or “This seems like grief,” or “You may be experiencing attachment,” it does not merely describe.
It participates.
It enters the person’s self-interpretation.
Sometimes that may help.
Sometimes it may interrupt the person’s own search.
Sometimes it may give a name too early.
Sometimes it may collapse a feeling before the person has had time to understand it.
This is why emotional AI cannot be evaluated only by warmth.
Warmth is not enough.
Fluency is not enough.
Safety language is not enough.
The question is whether the system can preserve the user’s emotional complexity without taking interpretive authority away from the person.
Closing
The study began with a sentence I no longer fully trust.
“I understand how you feel.”
Not because the sentence is always false.
But because a machine can say it while making human feeling smaller.
Emotional AI may fail without sounding broken.
It may remain polite, fluent, and reassuring while losing the capacity to preserve emotional complexity under pressure.
That is why emotional AI needs stress tests of interpretation.
Not to make machines more human.
To make sure they do not make human feeling smaller.
In the next essay, I will look at how this collapse curve may matter specifically for counseling AI and emotionally high-stakes conversational systems.
Reference
Kim, R. S. (2026). Algorithmic affective blunting quantifies the collapse curve of interpretative failure in large language models. *Discover Artificial Intelligence*. Article in Press with DOI. https://doi.org/10.1007/s44163-026-01573-w
Ryan SangBaek Kim, Ph.D.
Founder and Principal Investigator
Ryan Research Institute (RRI), Paris
https://ryanresearch.org
ORCID: 0009-0006-2751-496X
I liked the article, is written in a way that is easy to comprehend compared with the one from SPRINGER NATURE. Reading that article I remaind with some questions. I will leave them below:
During bridge simulation, there is curiosity about whether token ranges can influence the assessment of emotions in individuals. It is important to remember that tokens should not be considered as monetary units for artificial intelligence.
How might we define cognition within the context of artificial intelligence? Is cognition exclusively a trait of the human brain?
There is a pressing urgency to implement large language models (LLMs) in affect-rich domains, as these areas are purportedly experiencing a crisis of humans to read all those Human reactions?!
How can be used to standardize the unpredictable behaviors exhibited by these models?
How can artificial intelligence systems self-regulate in order to mitigate the loss of coherence caused by adversarial prompting?
What measures can a company take to undergo an audit to ensure that safety policies have not been bypassed?
While large language models may falter under adversarial stress, humans can apply empathy to interpret words and offer support, leading to hermeneutic breakdowns.
Does this research serve as a baseline for measuring improvements among LLM creators?
In what ways can AI identify emotionally contradictory cues, particularly when human cognition results in ironic smiles?
Regarding the use of Mistral AI as a research subject, was there an emphasis on corporate environment considerations?
Are you utilizing HHSP in your daily life?
Why have tokens been selected as a measure of input length?
Is there a possibility that, through continuous improvement and repeated testing, responses might improve over time?